In part 2 I hired an AI critic that told me my apps looked like templates. Here are seven of them on the day it first scored them, next to how they look now. Same phone, two weeks apart.
Consistently: the list became rings
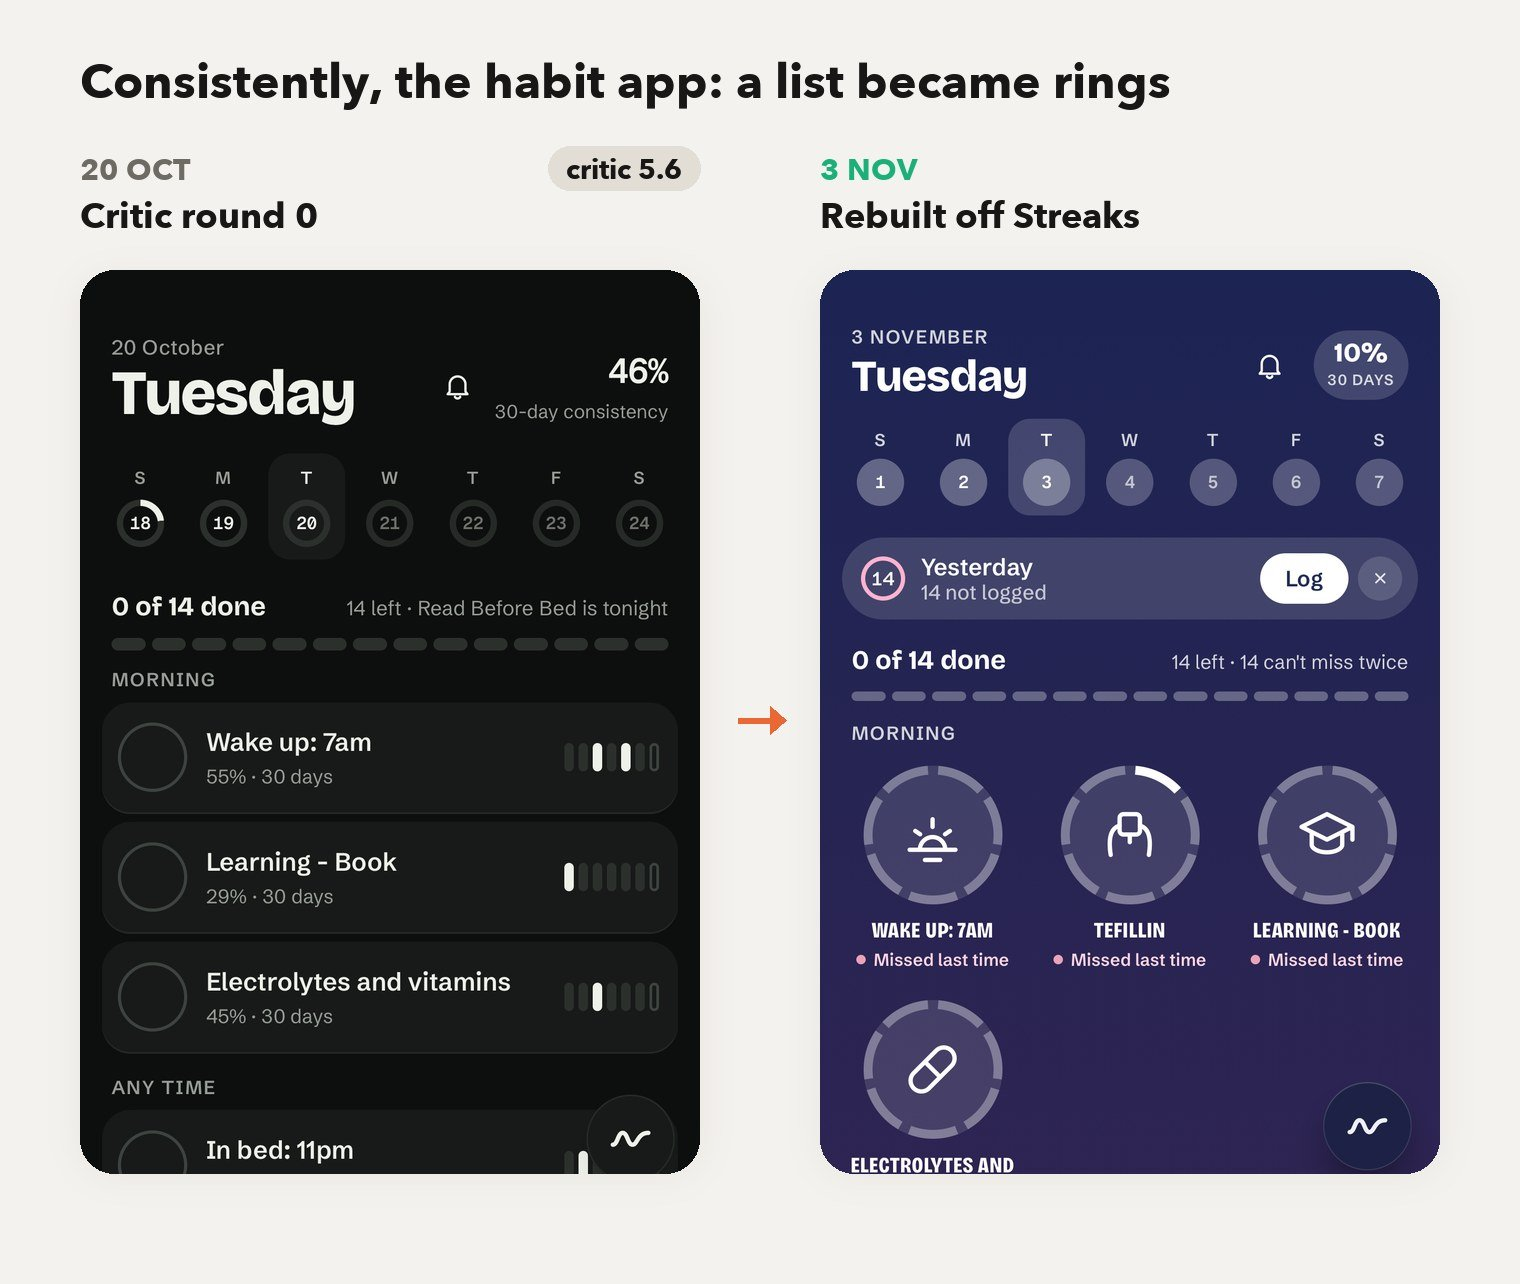
- Look at the left. It’s a clean dark card list. Fine, forgettable, and it scored 5.6 next to Streaks and Habitify.
- Two critic rounds took the average from 5.4 to 6.3. The coach chat hit 7.0, the best in the app.
- 27 Oct: navy and periwinkle. 3 Nov: I fed it Streaks’ real App Store screens, and now every habit gets its own ring on a blue-to-pink gradient.
- Born 9 Oct to replace Habitify, 28 commits in. Habitify, consider yourself fired.
Four apps, one move: copy the leader’s homework
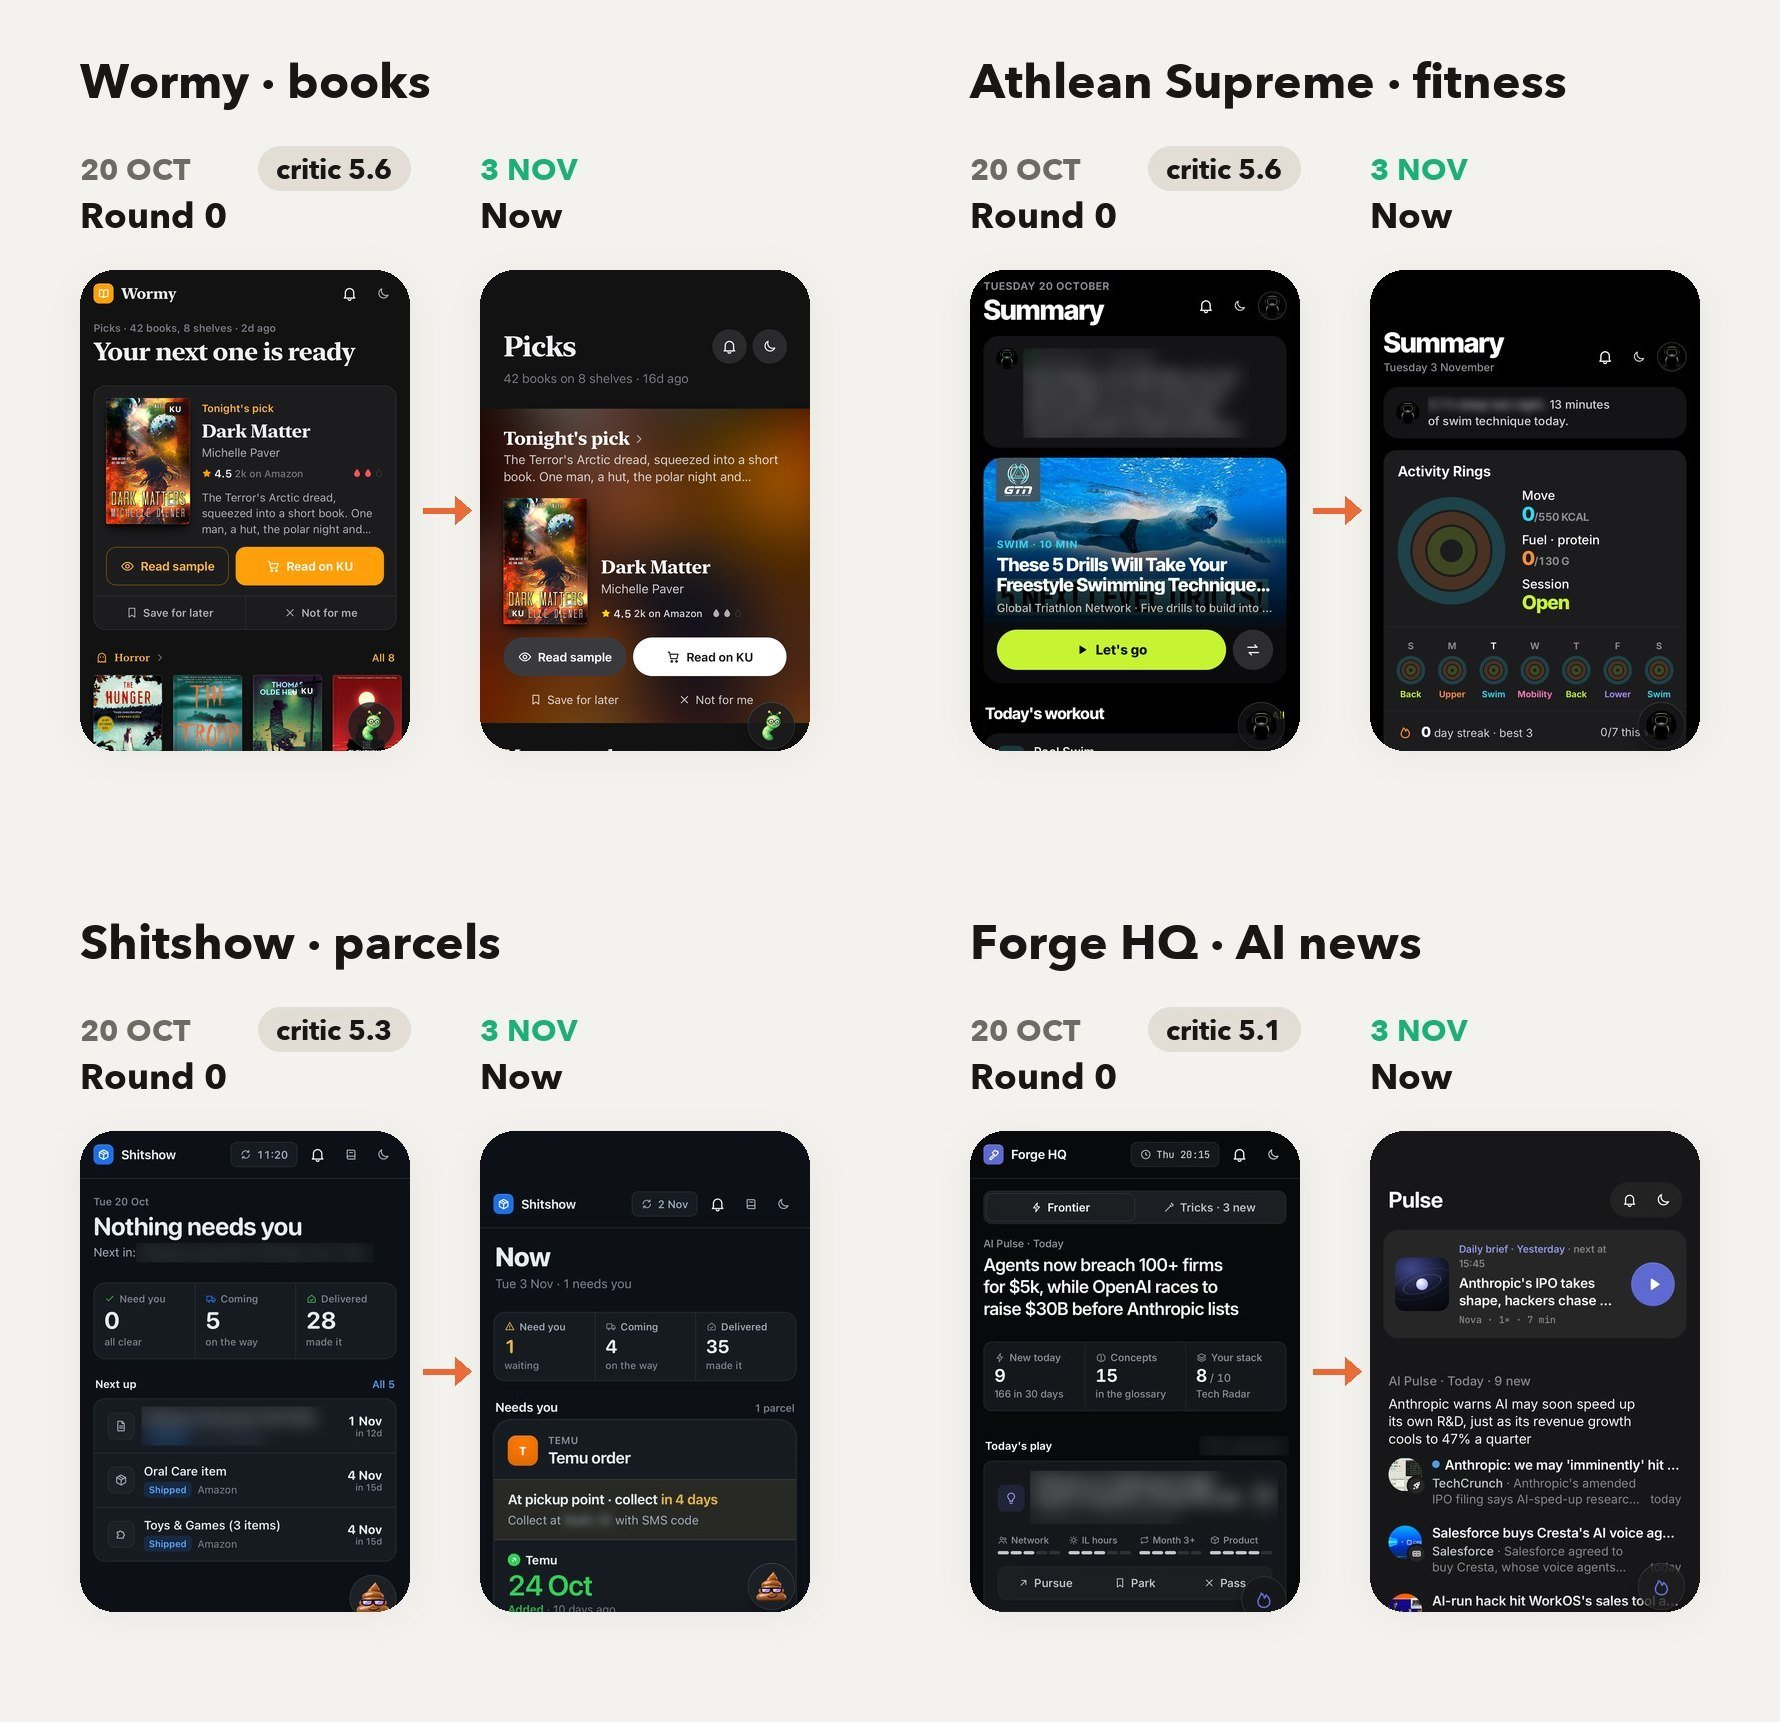
- Wormy is where this all started. On 7 Oct I called the first “family look” of these apps “clunky… juvenile… like artifacts.” Against Apple Books it went from 5.5 to 6.4 by round 5, with the book page at 7.4. On 3 Nov it was rebuilt off Apple Books’ real screens.
- Athlean Supreme went from 5.3 to 6.1 in one afternoon. Look at the top of Today: it now leads with Activity Rings, built from Apple Fitness, MacroFactor and Function Health screens.
- Shitshow is the oldest of the lot (30 Sep, 78 commits). The new rule is that “every parcel is a flight,” Flighty-style, so the next parcel is one big card with its countdown.
- Forge HQ had four tabs and six sub-views. On 1 Nov I cut that to three (Pulse, Apps, Inbox) and gave every story a picture, then rebuilt it off Linear’s Inbox.
- The blurred bits are blurred on purpose.
Built to Last and Anchorman: the two that got pictures
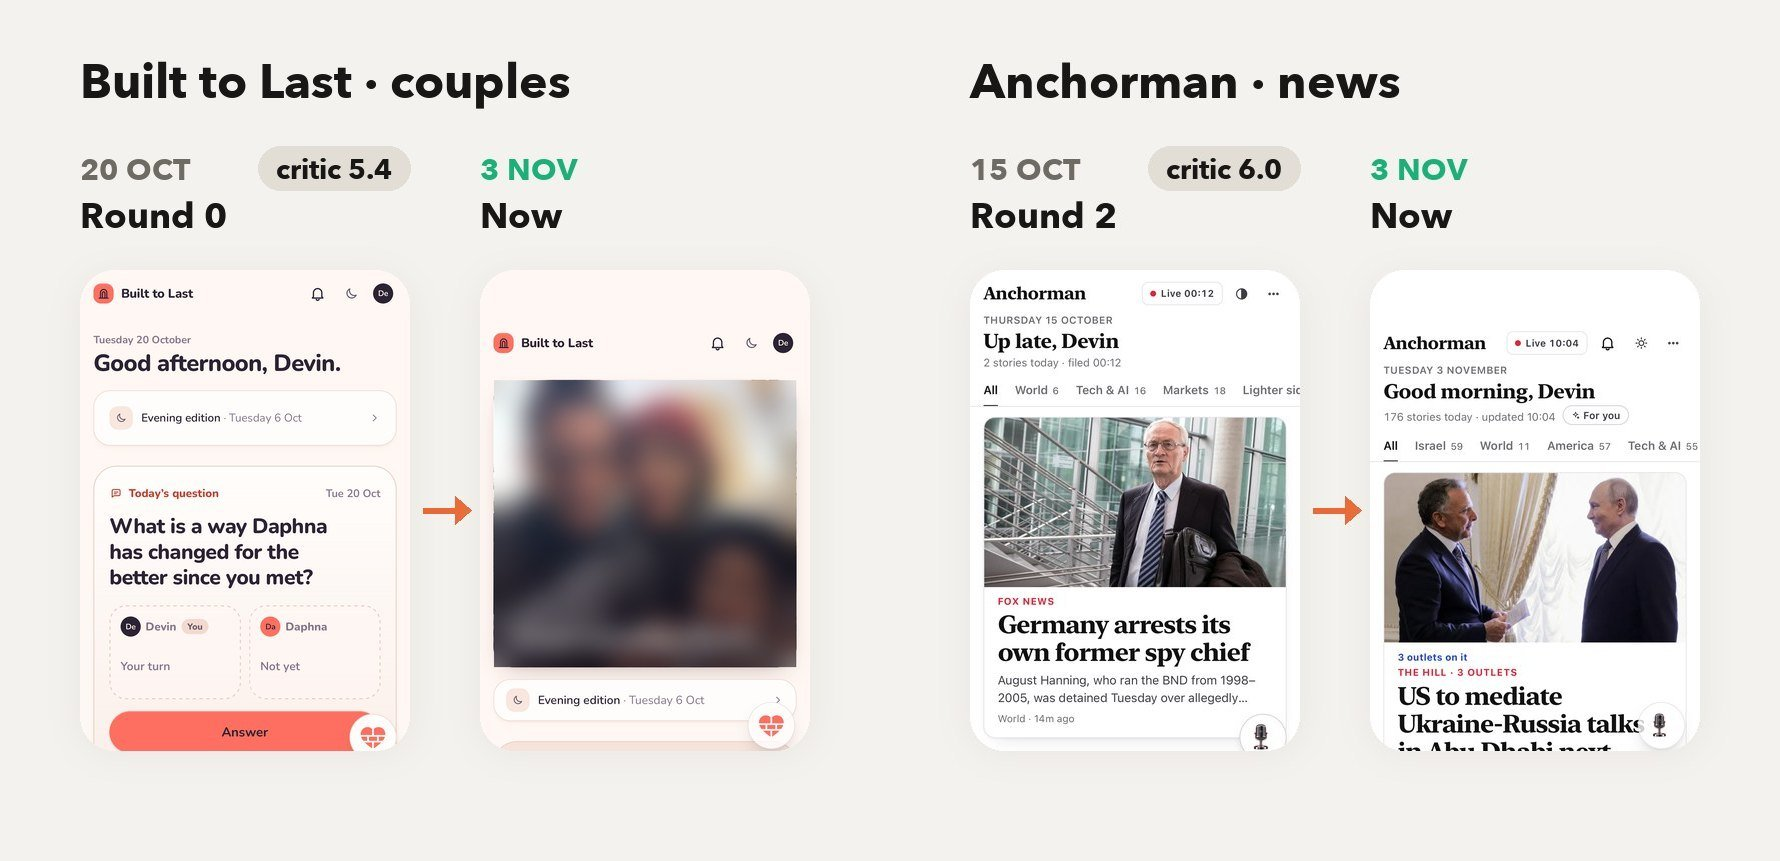
- Built to Last is the couples app for me and Daphna. It scored 5.2 to 5.9 against Paired. Since 29 Oct, Today opens on a photo of the two of us, and since 3 Nov every lesson track has its own painted picture.
- Anchorman is my own Google News. It went from 5.2 to 6.0 against Apple News on 15 Oct. On 1 Nov it got Google News-style blocks and a picture on every story.
- The pattern across all seven: every first-round average landed between 5.2 and 5.5, and after the critic rounds they sat at 5.9 to 6.4. Each round costs about $0.60 on the API, or nothing on the Max plan.
- No score on the right-hand side because the 3 Nov rebuilds haven’t been re-scored yet. Yalla, round next.
- How I shot them: “before” is the critic’s own capture (WebKit, iPhone 15 Pro size). “Now” is each app’s current GitHub version running locally on a copy of its data, with paid APIs off.
Also today
- Meat Night: the night page now looks like a Beli restaurant page. You can say you’re in or out for Tuesday right on Tonight, and it nudges whoever is holding up the reveal.
- The fleet critic now passes a clean screen at 7.0 instead of 8.0. Its scores also refresh in the control room without a reload.